

Server Monitoring Metrics That Actually Matter (And Ones That Don't)
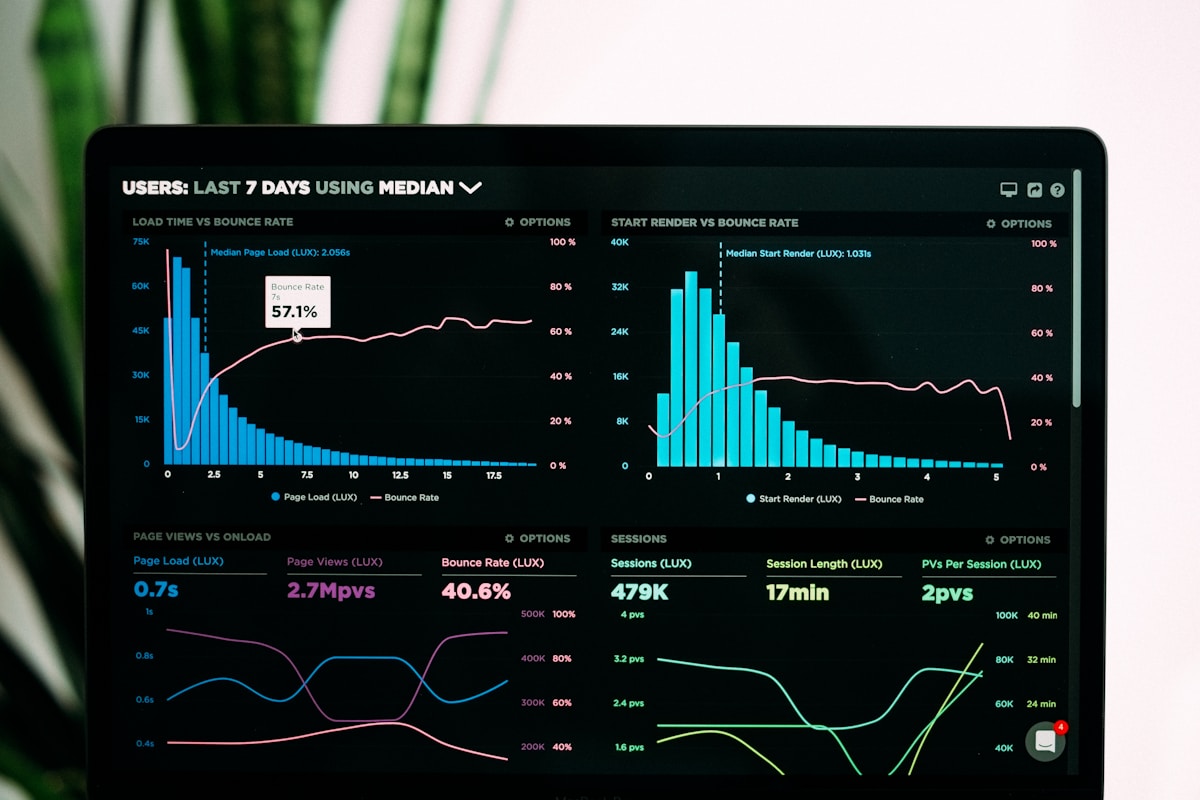
Server monitoring dashboards can display dozens of metrics simultaneously, and it's genuinely easy to either ignore them entirely (checking only when something's already broken) or stare at them without knowing which numbers actually matter for your specific situation. Here's a practical guide to the metrics genuinely worth your regular attention.
CPU Usage: Look at Trends, Not Just Snapshots
A single high CPU reading isn't automatically concerning — brief spikes during legitimate traffic bursts or scheduled tasks are normal. What matters more is sustained high CPU usage over time, and specifically whether it correlates with degraded response times. A server consistently running at 90%+ CPU during normal (not peak) traffic is a much stronger signal of a genuine capacity problem than an occasional brief spike during a traffic surge.
Memory Usage and Swap Activity
Available memory matters less on its own than whether your server is being forced into swap usage — writing memory contents to disk because physical RAM is exhausted. Since disk access is dramatically slower than RAM, any meaningful swap activity is a strong signal that your server is memory-constrained in a way that's actively degrading performance, not just a number worth casually noting.
Response Time Percentiles, Not Just Averages
Average response time can be dangerously misleading — a server with mostly fast responses and a few extremely slow outliers might show a perfectly reasonable average while still delivering a genuinely poor experience to a meaningful fraction of actual visitors. Looking at percentiles (particularly p95 and p99 — the response time experienced by the slowest 5% and 1% of requests) gives a much more honest picture of your actual worst-case user experience, which averages alone systematically obscure.
Error Rate Trends
Track your error rate (percentage of requests returning 4xx/5xx status codes) as a trend over time, not just an absolute current number. A gradually climbing error rate, even while still numerically "low," often signals an emerging problem worth investigating before it escalates into a more severe, user-visible incident.
Database Connection Pool Utilization
If your database connection pool is regularly near its configured maximum, this is an early warning sign worth acting on before it becomes a full bottleneck — requests queuing for available connections directly translates to increased response times, and eventually to outright request failures once the queue itself becomes unreasonably long.
Disk Space (Often Overlooked Until Critical)
Running out of disk space can cause a surprisingly wide range of failure modes — failed writes, database corruption risk, log files that can no longer be written. Unlike CPU or memory pressure, which typically degrade performance gradually, disk space exhaustion often causes a more sudden, complete failure once the threshold is crossed, making proactive monitoring with reasonable advance warning thresholds particularly valuable here.
Queue Length for Background Jobs
If your application uses background job processing (email sending, image processing, report generation), a growing, unprocessed queue backlog indicates your worker capacity isn't keeping pace with incoming job volume — an early, often invisible-to-users precursor to jobs eventually failing outright or users experiencing unacceptably long delays for asynchronous operations they're expecting to complete promptly.
SSL Certificate Expiration Countdown
As covered in more depth in our SSL guide, tracking days remaining until certificate expiration (with alerts at reasonable advance thresholds) prevents one of the most avoidable, embarrassing outage categories entirely.
Uptime Percentage Over Rolling Windows
Beyond simple current status, tracking your actual uptime percentage over rolling 30-day and 90-day windows gives you concrete, objective data for evaluating whether your infrastructure and hosting are actually meeting your reliability requirements — connecting back to our SLA verification guide, this is the data that turns a vague feeling about reliability into an objective, actionable number.
Focus on Correlation, Not Isolated Metrics
The most valuable insight often comes from correlating multiple metrics together — elevated response times that correlate with high database connection pool utilization point toward a database bottleneck specifically, while elevated response times correlating instead with high CPU usage point toward a different, distinct root cause requiring a different fix entirely. Dashboards that let you view multiple relevant metrics together, aligned on the same timeline, make this kind of correlation analysis dramatically easier than reviewing each metric in isolation.
The Bottom Line
Not every available metric deserves equal attention — prioritizing the ones that most directly correlate with actual user-facing experience (response time percentiles, error rates, uptime) alongside the resource metrics that typically precede and explain degradation (CPU, memory, disk, connection pools) gives you a genuinely actionable monitoring practice, rather than an overwhelming dashboard of numbers that's easy to ignore entirely in practice.